Transcription accuracy is measured as Word Error Rate (WER) — the percentage of words in the output that differ from the correct transcription. A WER of 5% on a 500-word transcript means roughly 25 words are wrong. A WER of 2% means about 10 are wrong.
Raw WER numbers tell you something, but not everything. The more important questions are: what kinds of errors occur, on what kinds of audio, and how do those errors affect actual usability? This guide sticks to what is published, then shows you how to measure the number that matters — the one on your own recordings.
What the published benchmarks say
Kajo runs one open-weight speech model on-device. Its developer publishes per-language error rates on the Common Voice 15 and FLEURS test sets, and describes the variant Kajo runs as having a minimal accuracy loss against its larger sibling. Independent benchmarks exist for the hard cases: on the Open Universal Arabic ASR Leaderboard (arXiv:2412.13788, Table 1), the model Kajo runs scores about 33% WER across dialect-heavy Arabic sets, versus about 30% for the full-size model. What the model is and why it fits on a laptop: the engine guide.
Most consumer cloud services do not publish WER. Rev advertises its human transcription as “99%+ accurate” (rev.com/pricing, checked 2026-09-27), which is plausible for good audio with experienced transcribers.
Kajo publishes no accuracy benchmark of its own. Until it can publish one with a reproducible method, the honest number is the one you measure below.
What affects accuracy most
Audio quality has a larger effect on WER than model choice. The factors that degrade accuracy, roughly in order of impact:
- Background noise: wind, HVAC, traffic, crowd noise
- Recording quality: phone microphone vs. a close condenser microphone
- Speaker characteristics: heavy regional accent, fast speech rate, soft-spoken delivery
- Number of speakers: single speaker is easiest; overlapping speech degrades every model
- Domain vocabulary: unfamiliar technical terms, proper nouns, acronyms
- Language: high-resource languages (English, Spanish, French) have lower WER than low-resource languages
Accuracy differences between models are smaller than the swing between a good and a bad recording of the same conversation.
Better recordings beat a cloud “cleanup” step
Some cloud services sell an enhanced-accuracy or cleanup pass that runs after upload. Whatever it does for the words, it also means the recording now lives on their servers, under their retention policy. Kajo has no such stage: it decodes once, on your machine, with one profile tuned for multi-speaker conversation. If a word is missed, the audio the model heard is on your disk for you to check.
What actually moves the number is upstream of any model:
- Mic placement. A close microphone beats a room microphone, and a lapel mic per speaker beats one in the middle of the table.
- Noise at the source. Turn off HVAC and fans where you can, and keep keyboards and paper away from the mic.
- One channel per talker. Overlapping speech is the hardest case for both the words and the speaker labels; separate channels help both.
- Level, not loudness. Clipped audio loses words for good; a quieter, clean recording transcribes better than a loud, distorted one.
How to check accuracy on your own audio
The free allowance (5 files or 150 minutes, for life) is your benchmark:
- Pick a representative ten-minute clip — the microphone, room, accents, and vocabulary you actually work with.
- Transcribe it on-device and read the transcript against the audio.
- Count the corrections you make. Twenty corrections in a thousand words is a 2% WER on your audio; two hundred is 20%.
- Test the hard cases separately: two speakers talking over each other, a phone recording, a switch into a second language.
Ten minutes of your own tape tells you more than any published table.
The review path inside Kajo
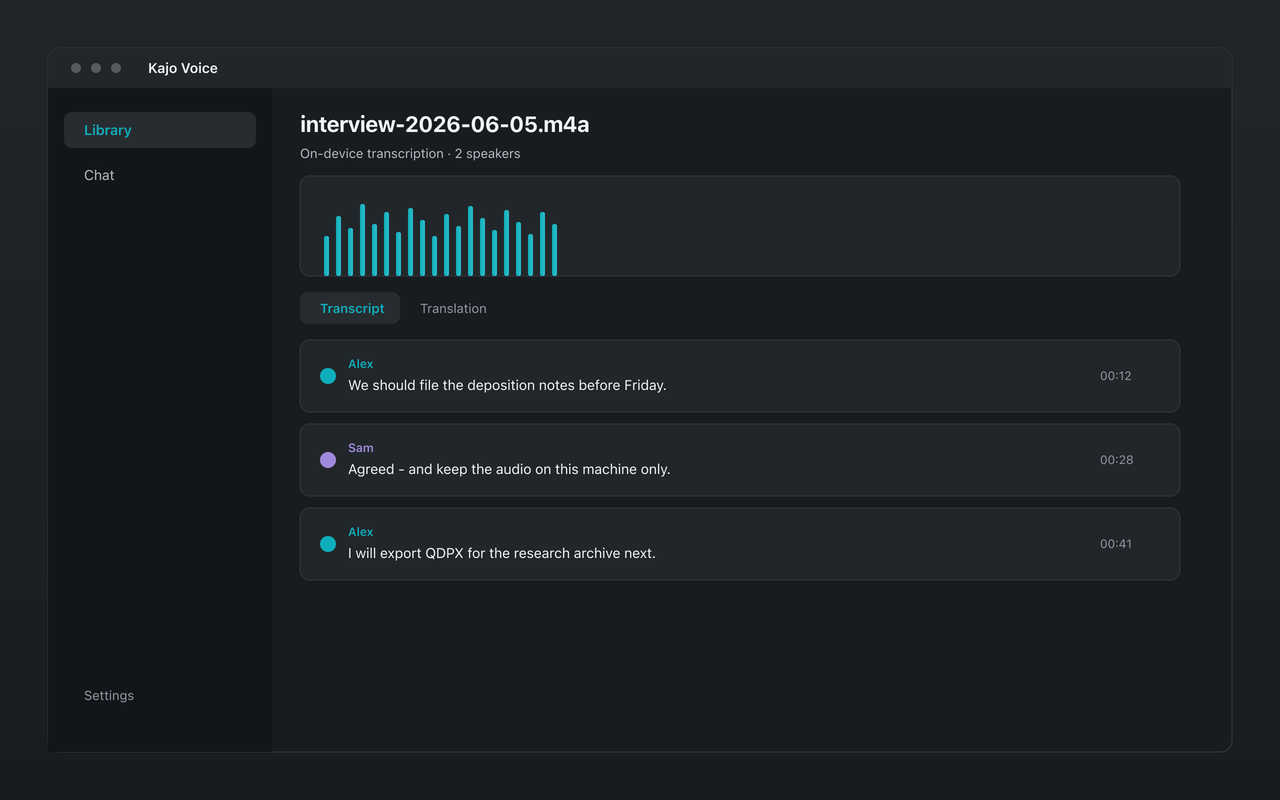
- Inline correction. Fix a misheard name with inline segment edit; the correction carries into search, exports, and cited chat without re-transcribing.
- Speaker labels. Kajo labels speakers automatically per recording, for up to eight speakers. Overlapping speech, more than eight speakers, and back-to-back monologues by similar voices are where labels go wrong — rename, reassign turns, or restore the automatic labels, and review attribution against the audio when it matters.
- Answers carry a review line. Summaries and drafts come from Chat, and every question box and exported answer says “Review before this leaves this machine.” They are a starting point, not a record.
- One decode profile, not a menu. Every recording decodes under the same conversation-tuned settings, so the same file never produces two different transcripts because of a setting you forgot you changed.
Code-switching follows the model’s behaviour: one language decision per recording, a multilingual vocabulary, so short switches usually come through as spoken and long runs in the second language are the spans to review.
The accuracy ceiling: when to use human transcription
For audio where word-for-word accuracy is legally required (court proceedings, depositions, regulatory filings), or where audio quality is genuinely poor (decades-old tape, field recordings in noisy environments), human transcription services such as Rev’s human tier ($1.99 per audio minute) remain the standard.
AI transcription — on-device or cloud — saves enormous time and cost for the majority of use cases. It is not a replacement for human review when the stakes of an individual error are high.
The practical recommendation: use AI transcription for drafting, search, and cited chat; use human review (yourself or a professional) when the transcript will be published, submitted as evidence, or relied on for high-stakes decisions.