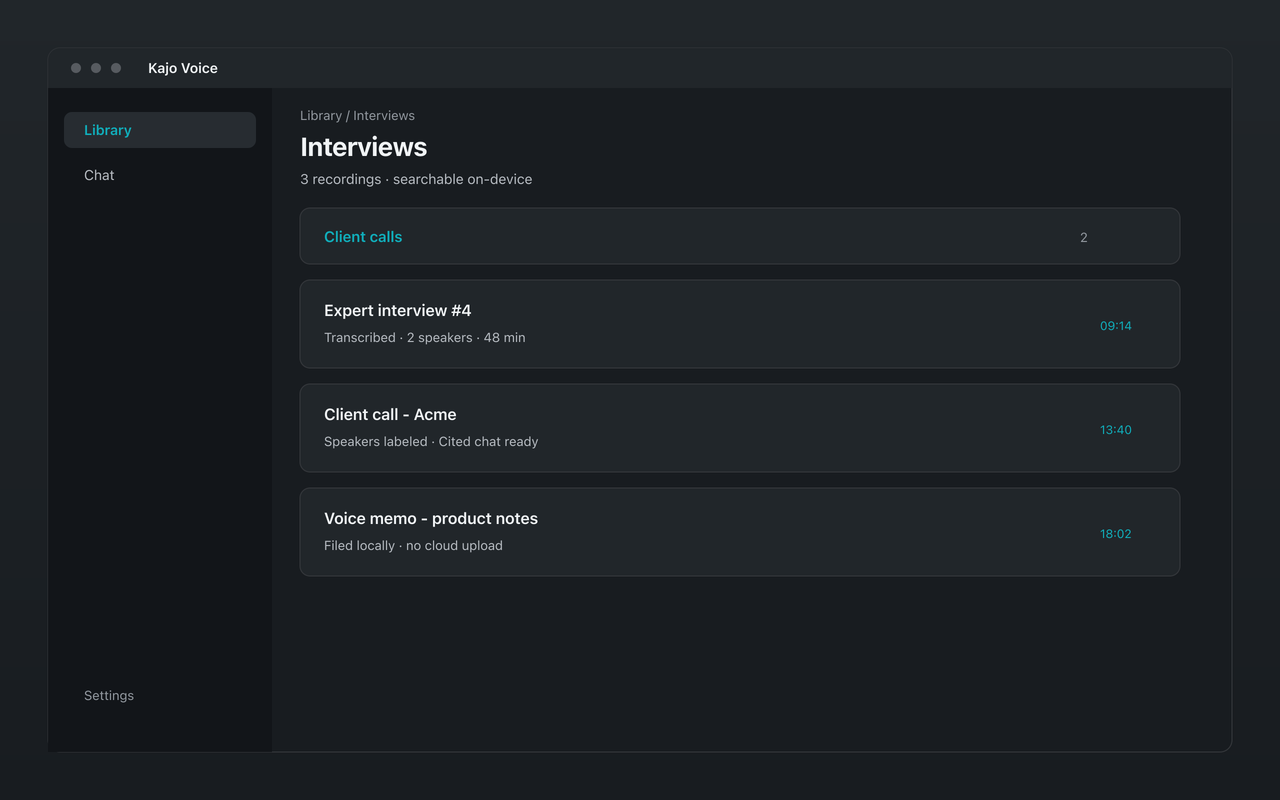
Most polished voice-AI desktop apps treat Linux as an afterthought — or skip it. Researchers, journalists, and engineers who live on Linux end up stitching together command-line speech recognition, ad-hoc Python environments, and copy-paste into an editor. That works until you want a real library, exports, and answers you can check, without maintaining a science project.
Kajo Voice ships the same local-first app on Linux as on Mac and Windows: import audio or video, transcribe it on-device with speaker labels, translate it, and ask a folder of recordings questions with a local Gemma 4 model — everything kept in a private, searchable library. Every Linux release comes as .deb, .rpm, and AppImage, for x86_64 and ARM64.
The Linux gap across voice AI tools
None of these seven products ships a native Linux app. Several run in a browser on Linux — with your audio processed in their cloud.
| App | Native Linux | Where it does ship |
|---|---|---|
| Granola | ❌ | macOS, Windows, iOS, Android — no Linux build, no public Linux roadmap |
| Wispr Flow | ❌ | macOS, Windows, iOS, Android — Linux listed as unsupported (waitlist only) |
| Otter.ai | ❌ | macOS and Windows desktop apps, web, mobile — browser only on Linux |
| Heidi Health | ❌ | Windows and macOS desktop apps, web, mobile — browser only on Linux |
| Plaud Desktop | ❌ | macOS and Windows |
| Krisp | ❌ | Windows and macOS — Linux and ChromeOS unsupported |
| Microsoft Copilot Voice | ❌ | Windows, macOS, web, iOS, Android — browser only on Linux |
| Kajo Voice | ✅ | .deb · .rpm · AppImage — x86_64 and ARM64 |
Why most voice AI tools skip Linux
Consumer AI apps usually launch on macOS first, because that is where early adopters are. The trouble is that macOS-first tends to become macOS-only. Meeting recorders lean on each platform’s system-audio capture path — on macOS, the Screen & System Audio Recording permission — so every new platform means another capture backend to write and support. Linux (PipeWire or PulseAudio) would be a third. For apps that already ship on Windows, Linux is a packaging and support decision that keeps losing to feature work.
So in 2025, when StatCounter’s US figures began showing Linux on more than 5% of desktops in some months, the major voice AI tools were still “macOS and Windows only.” The people on those Linux desktops — developers, researchers, sysadmins, privacy-minded professionals — are often exactly the ones who would rather not upload their recordings anywhere.
Why Kajo runs natively on Linux
Kajo is import-first: you drop in files you already have, and it transcribes them on your machine. There is no system-audio capture path to port. Decoding and transcription use cross-platform engines (ffmpeg and whisper.cpp), the speaker-labelling and chat engines run as native Linux binaries on x86_64 and ARM64, and the app itself is the same codebase on every platform.
The result is the same app, not a port: on-device transcription, speaker labels, translation, the private searchable library, cited chat, and every export format. The one-time Lifetime purchase unlocks the same things on every platform.
Why Linux users get stuck with CLIs
The open-source speech ecosystem is excellent on Linux. whisper.cpp, faster-whisper, and related tools run well. What they do not give you out of the box:
- A durable library of recordings, with transcripts in a local database
- Folder organization for multi-year archives
- Automatic speaker labels per recording
- Questions across a folder, answered with citations by a local model
- One-click exports (SRT, DOCX, QDPX, and the rest of the format list)
You can assemble those pieces, and many people do. The cost is time, glue code, and a workflow you cannot hand to a non-engineer collaborator on the same study.
Hardware expectations
On Linux, the speech model runs on the CPU — Kajo’s Linux build has no GPU path for it — so queue batches and let them run. Speaker labelling runs on the CPU too, on x86_64 and ARM64 alike. On x86_64, the chat model can use a GPU through its own runtime and falls back to the CPU when it cannot; on ARM64 it runs on the CPU.
- RAM: 16 GB minimum. Kajo itself uses about 6 GB with the chat model loaded and about 8 GB with everything running; the rest is headroom, so the machine stays usable while a batch works.
- Disk: Setup downloads ≈7 GB of models once, before first use; everything runs offline afterwards.
Throughput varies with CPU generation and thermal limits. The same model produces the same transcript on Linux as on macOS; only the speed changes.
A Linux-native archive workflow
Intake. Keep a project directory on disk (~/research/study-a/, with an incoming/ folder inside it). Import manually, or point a watch folder (Lifetime) at the project directory so new exports from your recorder land in the library without a ritual. Moving a reviewed file out of it later is safe: its recording stays in the library, playing from Kajo’s own copy of the audio.
Transcribe. Queue the files; transcription and speaker labelling run locally. For a big batch, skim the first few transcripts for recurring names so you know what to watch for in review.
Review. Check names and speaker labels. When a term was misheard, edit the segment inline — the correction carries into search, exports, and cited chat without re-transcribing.
Analyze. Pin the folder in Chat and ask questions across it; answers cite the recordings they came from. Export QDPX, TXT, or JSON into the rest of your toolchain (NVivo on another machine, Python on the same box).
Retain. Back up the library with whatever backup tool your security policy already trusts. Local-first does not mean “no backups” — it means a transcription vendor is not your backup.
Privacy on multi-user and lab machines
Lab deployments often share hardware. Local-only transcription still needs OS-level access control: encrypted home directories, correct permissions on the data directory, and clear rules about who can log in. Kajo removes the cloud speech processor; it does not replace chmod, disk encryption, or institutional endpoint policy.
Once setup has downloaded the models, a lab machine can come off the network for good: transcription, speaker labels, translation, and cited chat keep working with no connection. Activating a Lifetime licence needs the network once; after that it keeps working offline with no expiry.
How this compares to “just use the CLI”
Use the CLI when you are building a headless pipeline, embedding speech recognition in a custom server, or scripting thousands of files with your own orchestration. Use Kajo when the job is a human-facing archive: browse, search, ask with citations, and export for collaborators who will never touch ffmpeg flags. See Kajo vs the command-line tools.
Many people keep both: CLI tools for specialized batch jobs, Kajo for the knowledge base they actually query day to day.
Pricing without a Linux surcharge
There is no “Linux edition” tax. Free includes the core loop up to 5 files or 150 minutes of audio, total. One payment ($49 launch / $99 standard) unlocks unlimited imports and Lifetime convenience (watch folders, batch export) on the desktop you already run. Your installed version keeps working forever — useful when grant-funded machines outlive SaaS subscriptions.
Common Linux questions
Which distributions does Kajo support? Ubuntu 22.04+ and Debian 12+ (.deb), Fedora 39+ and RHEL 9+ (.rpm), and any distribution that runs an AppImage — each for x86_64 (with an AVX2 processor) and ARM64. Kajo keeps your licence key and session in the desktop’s secret service, so it needs GNOME Keyring or KWallet running.
Kajo says it cannot find a keyring. What now?
It stores your licence key and session in GNOME Keyring or KWallet, and refuses to start rather than fall back to a store with a hardcoded password. On a tiling window manager such as i3, sway, or Hyprland, it can miss a keyring that is running; start it with --password-store=gnome-libsecret. Your library (kajo.db) and its backups are plaintext files on disk, so protect them with your account and disk encryption.
Does processing audio need a browser or an account? No. Processing happens on-device. Free needs no account at all; Lifetime needs a one-time online activation, which is separate from processing.
Can I use it for multilingual fieldwork? Yes. Transcribes 99 languages on your laptop — all on-device. Translation into 59 languages runs on-device with Gemma 4.
Does Otter or Wispr Flow have a Linux app? Not as of the date below: Otter runs in a browser on Linux, with your audio processed in its cloud, and Wispr Flow lists Linux as unsupported. Kajo is a native Linux app for people who want a private archive of their recordings rather than dictation or a meeting bot.
Bottom line
If your daily driver is Linux and you are tired of choosing between uploading to a Mac-centric SaaS and maintaining a personal speech-recognition lab, a real desktop app that never uploads is the missing middle. Start with a recording you would not put in a cloud notepad, confirm it works with the network off, then grow the library as the archive accumulates.